I’ve been running a team of LLMs instead of a single model, and the results are noticeably better. Wikipedia 1 source 1 Large language modelWikipedia
That sentence should feel wrong. More models means more latency, more tokens, more cost. The whole industry pushed us toward one-model-to-rule-them-all, and for a while that seemed reasonable. But a large language model is still a single perspective with a single set of blind spots, and no amount of prompt engineering fixes that. So I went the other direction. Wikipedia 1 source 3 Prompt engineeringWikipedia
What Mixture of Agents Actually Is #
Mixture of AgentsMixture of AgentsAn architecture where multiple LLM agents collaborate in layers, with aggregator agents evaluating and combining the outputs of reference agents to produce a single high-quality response. is exactly what it sounds like, once you stop assuming “mixture” means a training-time trick. It is not. Mixture of Agents runs at inference. You configure several reference agents, each backed by a different model or prompt, and one aggregator that sits above them. The aggregator acts as orchestrator: it sends your question to every reference agent, collects their answers, evaluates which parts are strongest, and composes a single response from the best fragments of all of them. arxiv 1 source 2 Mixture of Agentsarxiv
The mental model that stuck for me is a meeting. You do not talk to five people at once and try to synthesize their overlapping answers in your head. You talk to a manager after the team has discussed and filtered. The aggregator is that manager. One answer comes back, but it has been pressure-tested before it reaches you.
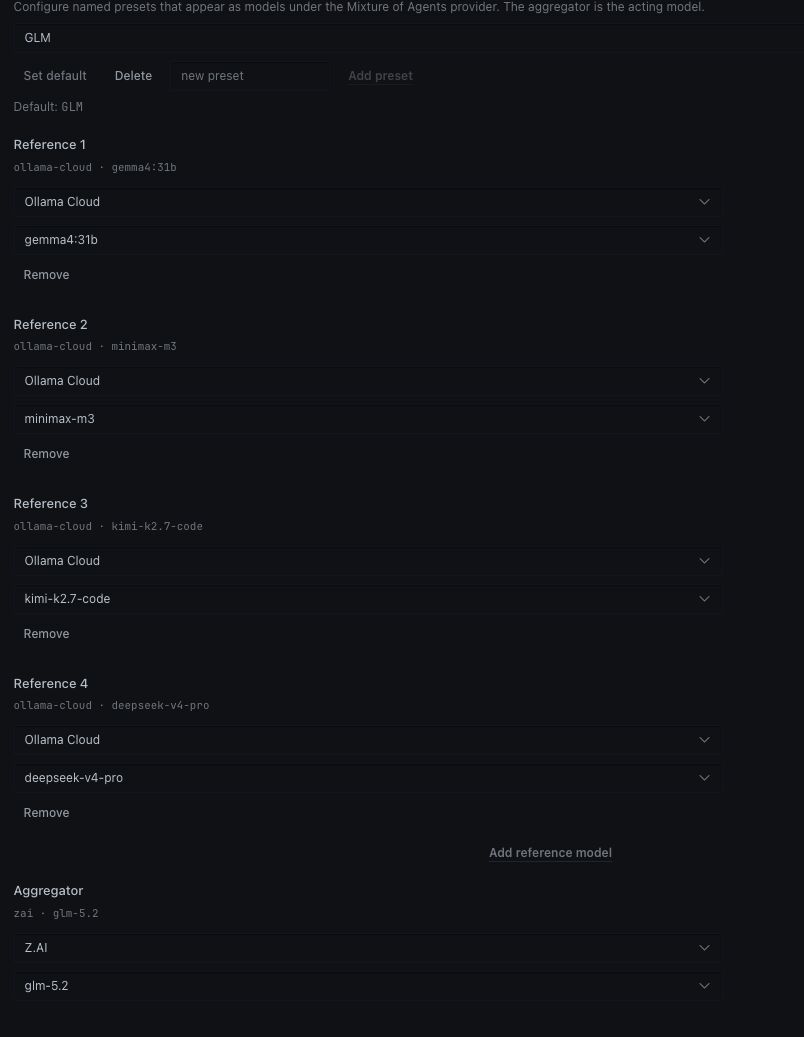
Nous Research shipped this inside Hermes Agent, and in the desktop app configuring MoA references and starting a conversation is straightforward. You pick your reference models, point them at the same aggregator, and start typing.
The Cost Question #
This is the part everyone worries about first, and it is the part that turned out cheaper than I expected.
MoA has built-in cost optimization. The reference agents do not see the full, decorated view of the conversation that you and the aggregator share. They get a stripped-down version: the question, the context needed to answer it, nothing else. That keeps the extra calls light. The aggregator does the heavy synthesis once, at the top, rather than asking every model to do the full job independently.
The net effect is that running a small team this way is cheaper than querying each model individually and reconciling their outputs yourself. Splitting token consumption across different providers also helps; smaller models can carry the lighter reference slots.
The Model Experiments #
This is where it got interesting, and where the single-model instinct really broke down.
I tried Gemma 4 31B as a reference agent and it changed the results dramatically. A smaller model, placed correctly inside an MoA layer, does not drag the output down. It contributes a distinct angle, gets evaluated against the others, and either its contribution is absorbed into the final answer or it is quietly dropped. You get the benefit of the smaller model’s perspective without inheriting its weaknesses.
NVIDIA Nemotron 3 Super was the other candidate. It is strong on paper, but in practice it was slow, and it hit the Needle in a HaystackNeedle in a HaystackA method for benchmarking long-context LLM performance by inserting a specific fact into a large document and testing whether the model can retrieve it. problem hard. In a Mixture of Agents setup, a reference model that loses track of a fact buried in a long context is actively harmful, because the aggregator trusts it to report accurately. Nemotron’s retrieval dropped exactly where the setup needed it most, so I set it aside. Wikipedia 1 source 4 Language model benchmarkWikipedia
The configuration that gave me the best results was a mix: one strong aggregator on top, a couple of larger reference models for depth, and a smaller, fast model like Gemma 4 31B in a reference slot to add a different read on the question.
Why This Changed My Mind #
I came into this assuming one good model, prompted well, would be enough. Two days earlier I had written about the harness gap – the idea that the model is only part of the system, and the harness around it does most of the work. Mixture of Agents is the clearest proof of that thesis I have run myself. The harness is not a wrapper here; it is the architecture. The aggregation layer is what makes the team a team.
If you have only ever talked to one LLM at a time, this feels like a category shift. It is the same instinct as sharpening tools – the setup does the work, and you stop fighting a single tool’s limitations by hand. For the kind of work I do now, this setup is a game-changer.